
Overview
Putki provides a commercial, enterprise-focused solution built on the Apache Hop open-source framework for data workflows. The platform addresses production challenges including stability, scalability, security, and support for organizations running data integration at scale. Putki bridges open-source software capabilities with enterprise-grade reliability and performance requirements.
In the news
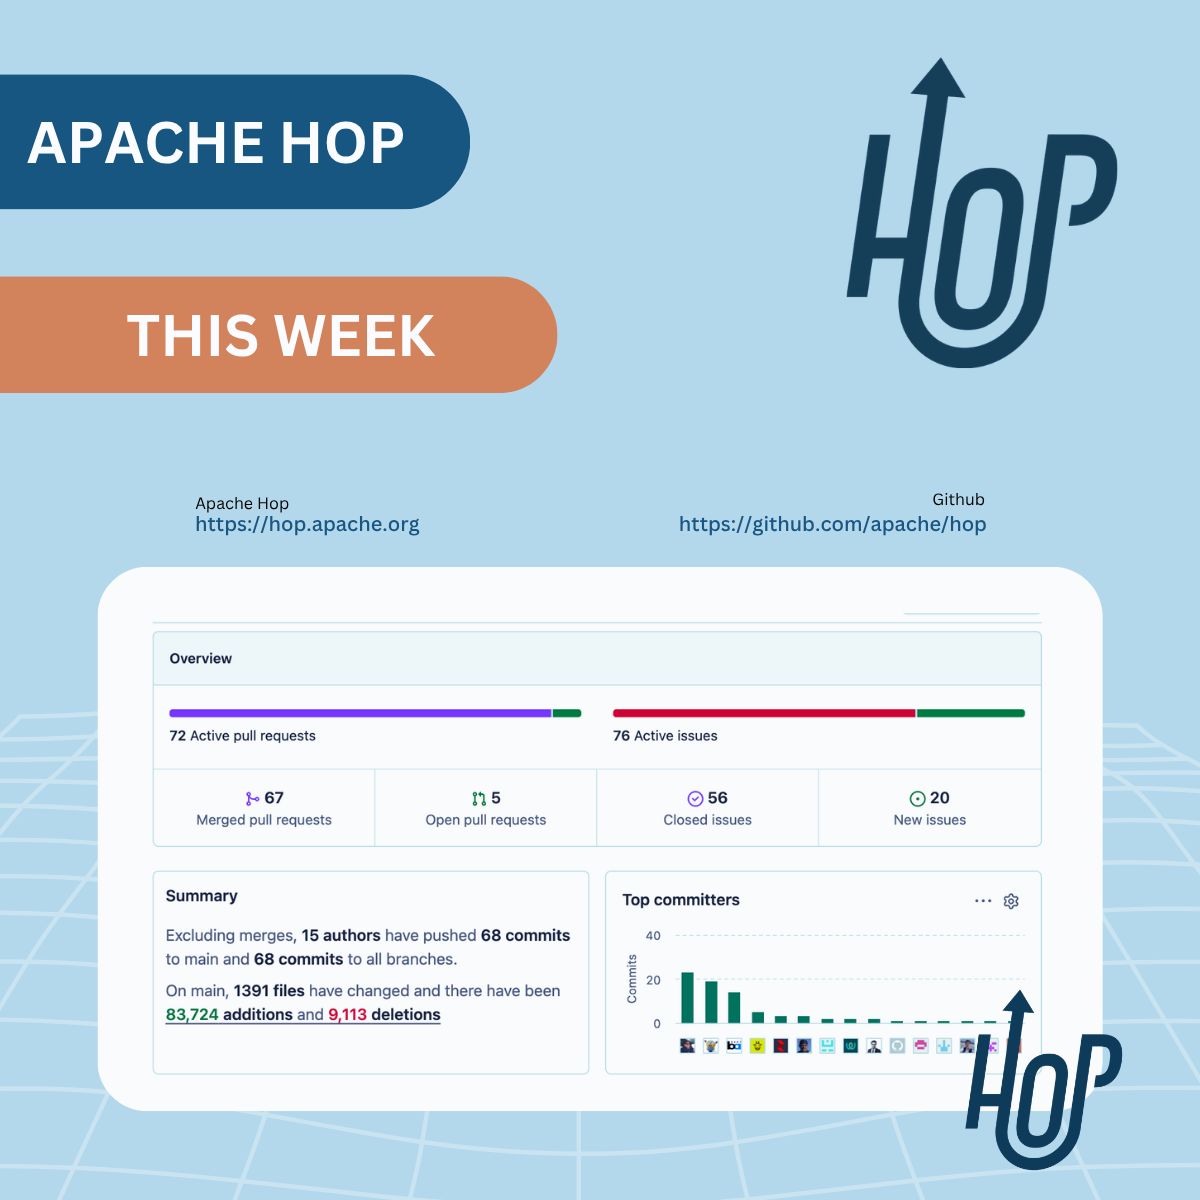
- Something changed this week. 𝗦𝗲𝗽 𝟭𝟬-𝟭𝟳: 67 PRs merged, 56 issues closed, 11 contributors. The numbers are impressive, but the interesting part is where the project is heading. The biggest addition this week is 𝗽𝗴𝘃𝗲𝗰𝘁𝗼𝗿 𝘀𝘂𝗽𝗽𝗼𝗿𝘁, with new upsert and search transforms. Together with the new 𝗩𝗲𝗰𝘁𝗼𝗿 𝘃𝗮𝗹𝘂𝗲 𝘁𝘆𝗽𝗲 for embeddings and the 𝗔𝗜 𝗔𝗱𝘃𝗶𝘀𝗼𝗿 𝗽𝗹𝘂𝗴𝗶𝗻 𝗳𝗿𝗮𝗺𝗲𝘄𝗼𝗿𝗸, Apache Hop is starting to build a solid foundation for AI and vector-based workflows. A Text Chunker transform
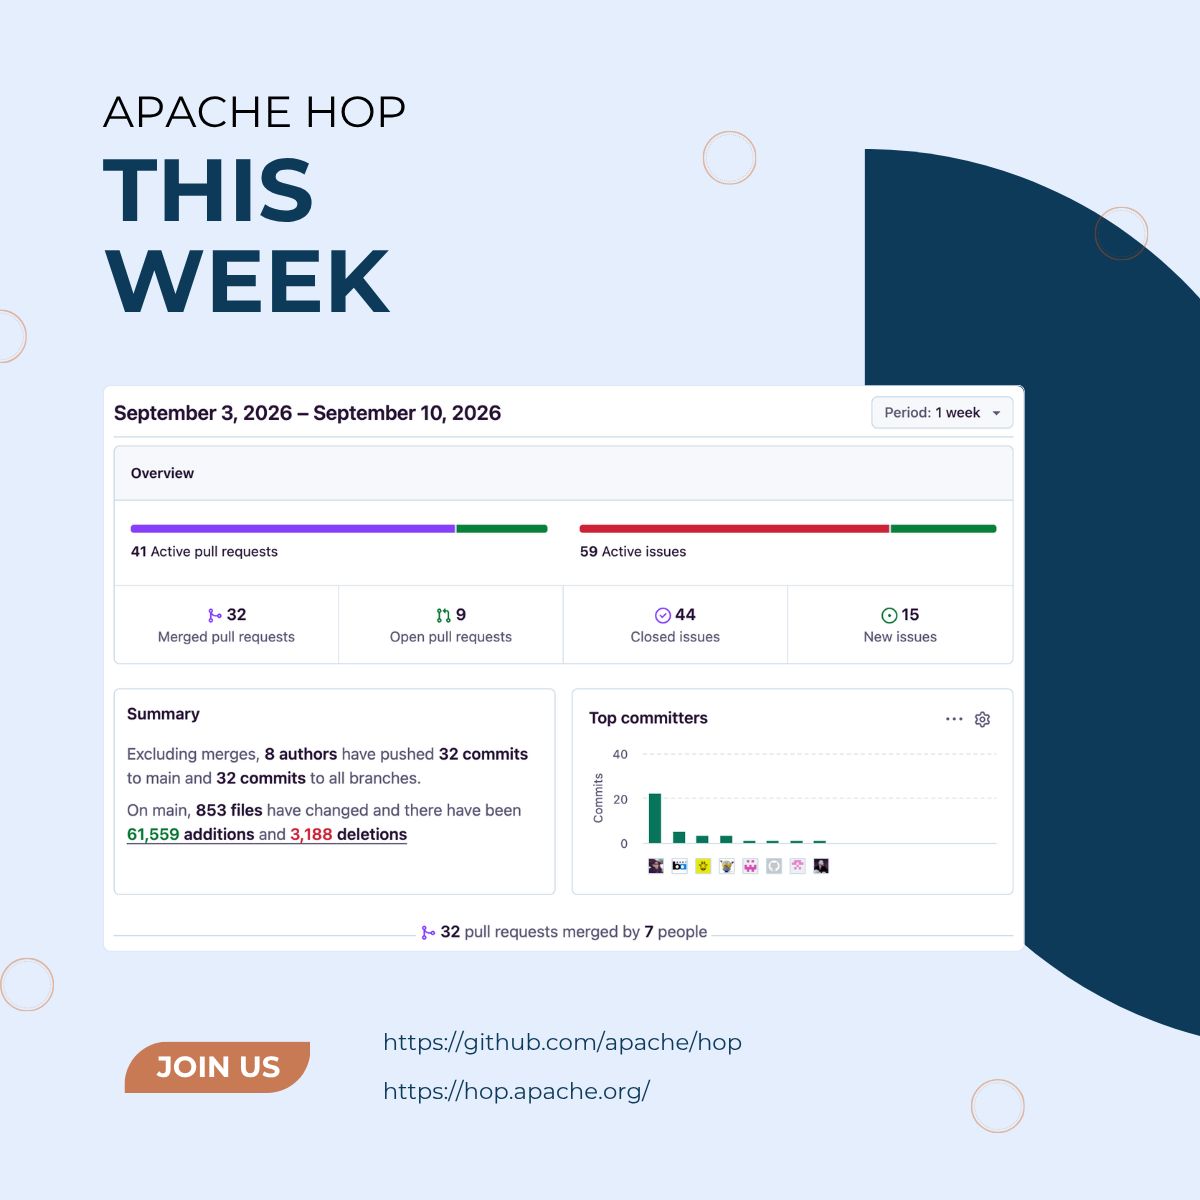
- 𝗦𝗲𝗽 𝟯-𝟭𝟬. 𝟯𝟮 𝗣𝗥𝘀 𝗺𝗲𝗿𝗴𝗲𝗱. 𝟰𝟰 𝗶𝘀𝘀𝘂𝗲𝘀 𝗰𝗹𝗼𝘀𝗲𝗱. 𝟳 𝗰𝗼𝗻𝘁𝗿𝗶𝗯𝘂𝘁𝗼𝗿𝘀. The standout is probably the new 𝗗𝗮𝘁𝗮𝗯𝗮𝘀𝗲 𝗣𝗲𝗿𝘀𝗽𝗲𝗰𝘁𝗶𝘃𝗲. Instead of jumping into the SQL editor dialog, you can now browse tables, inspect data, and navigate your database directly from within Hop. The new WebHDFS / HttpFS / Knox VFS plugin is another great addition. If your organization exposes HDFS over HTTP, you can now connect without installing the Hadoop client libraries. Hop GUI also gained a notification
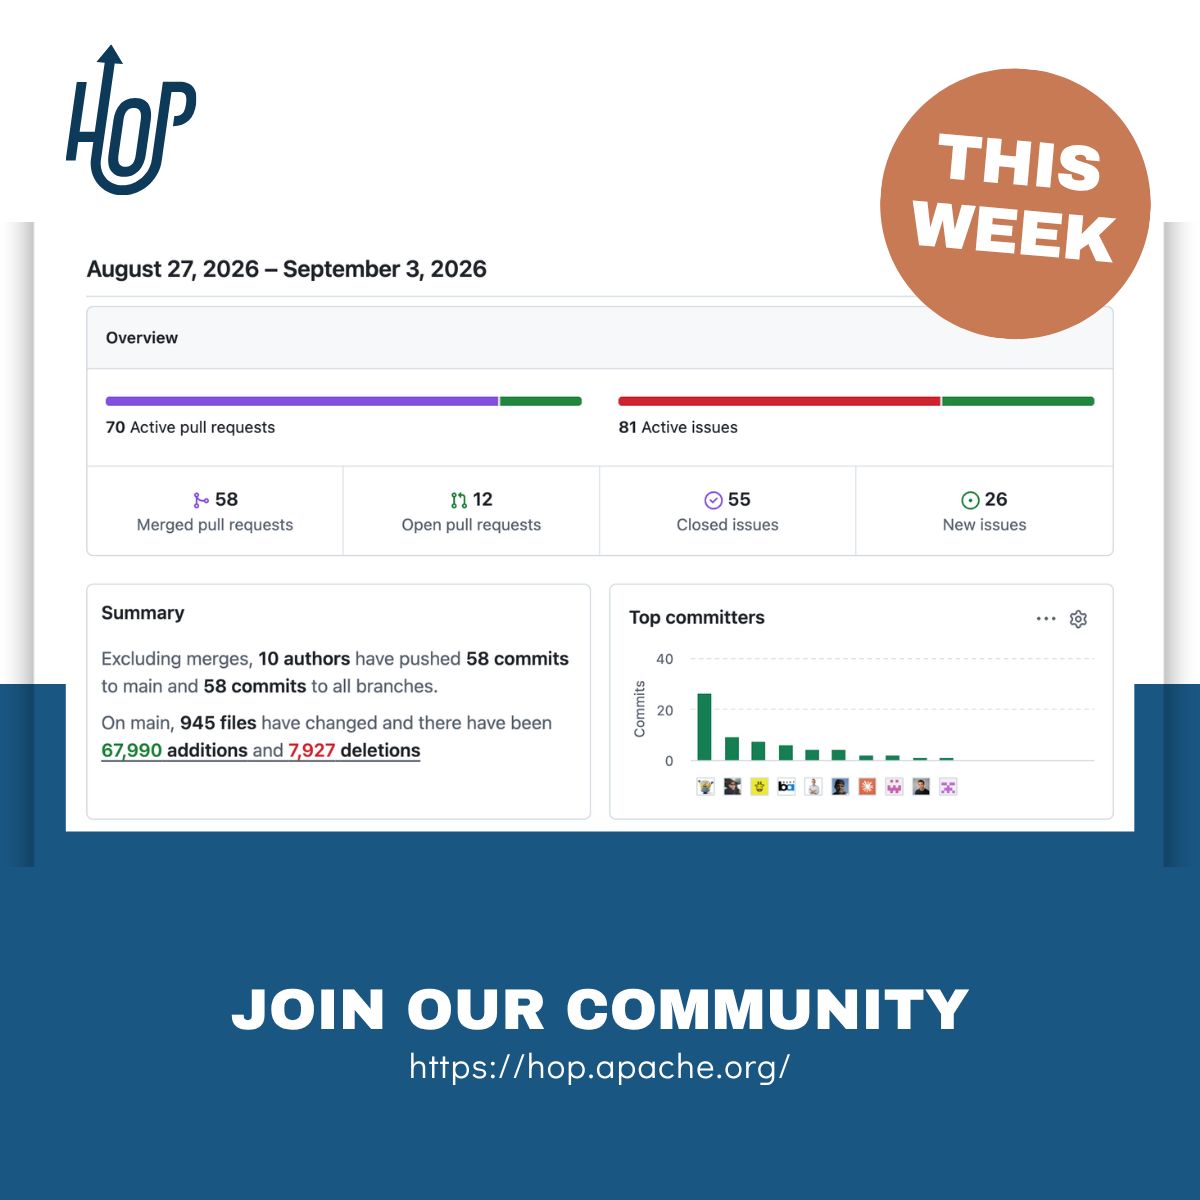
- 𝗔𝘂𝗴 𝟮𝟳 - 𝗦𝗲𝗽 𝟯: 𝗔𝗻𝗼𝘁𝗵𝗲𝗿 𝘄𝗲𝗲𝗸 𝗼𝗳 𝘀𝘁𝗲𝗮𝗱𝘆 𝗽𝗿𝗼𝗴𝗿𝗲𝘀𝘀 𝗳𝗼𝗿 Apache Hop. 58 PRs merged • 55 issues closed • 9 contributors This week introduced 𝗹𝗶𝗻𝘁𝗶𝗻𝗴 for pipelines, workflows, and metadata, making it easier to catch naming issues, missing connections, and other common problems directly from the GUI. A new 𝗗𝗮𝘁𝗮𝗯𝗮𝘀𝗲 𝗩𝗮𝗹𝘂𝗲 𝗩𝗮𝗹𝗶𝗱𝗮𝘁𝗶𝗼𝗻 transform helps validate data against database constraints before loading it, and the 𝗢𝘂𝘁𝗽𝘂𝘁 𝗧𝗿𝗮𝗻𝘀𝗳𝗼𝗿𝗺 𝗠𝗲𝘁𝗿𝗶𝗰𝘀 transform
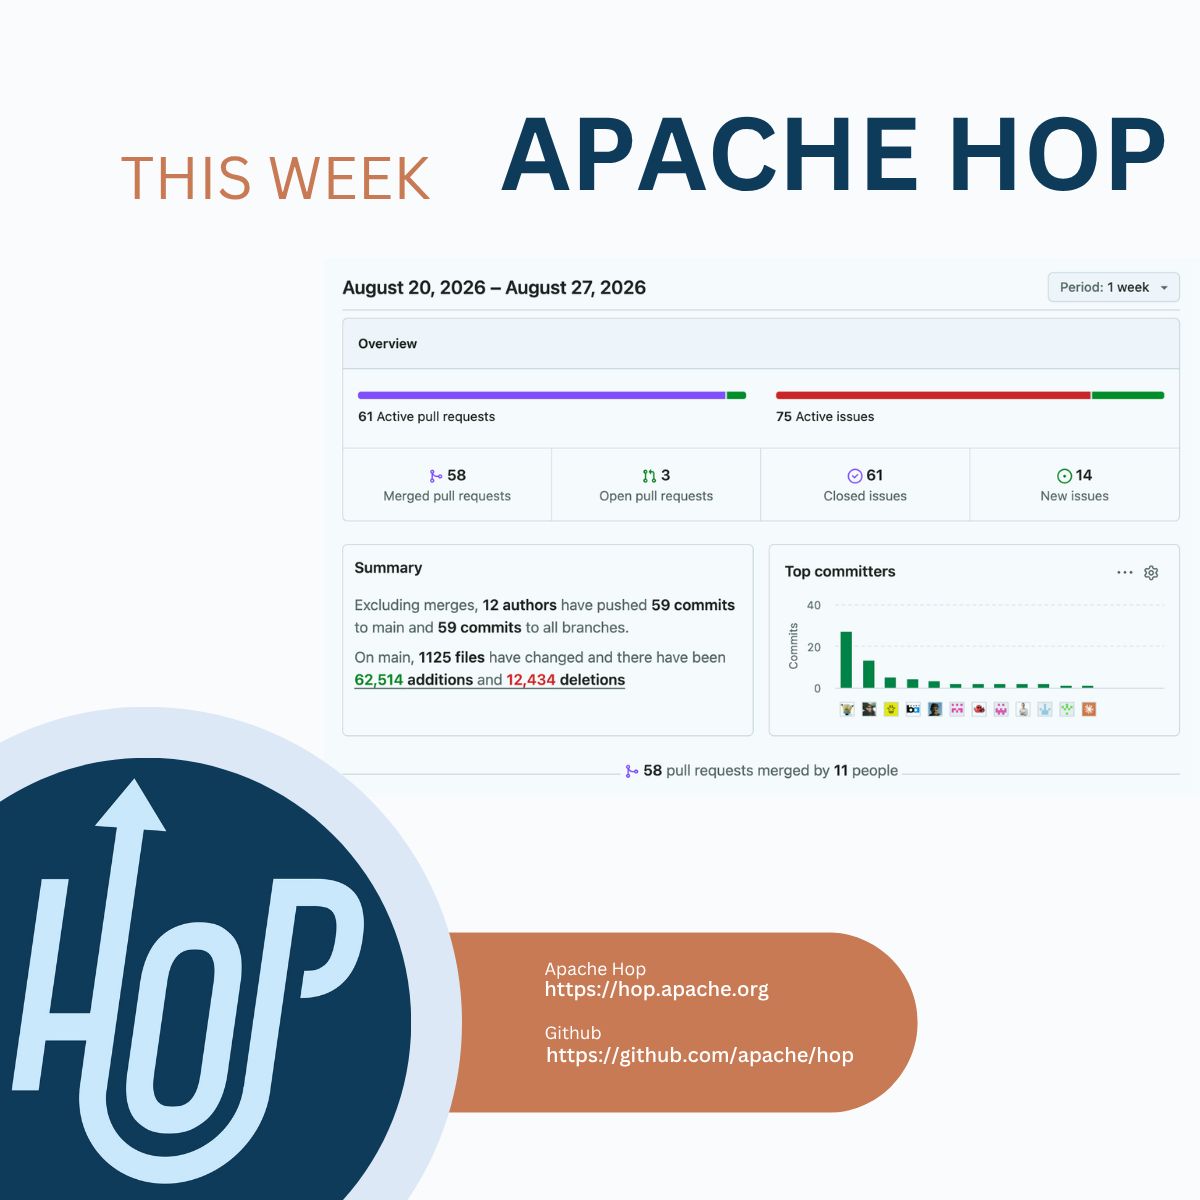
- Two strong weeks in a row. Between Aug 20–27, Apache Hop merged 58 PRs, closed 61 issues, and saw contributions from 11 people. In total, 1,125 files changed. Development hasn't slowed down since the 2.19 release. One of the biggest additions this week is the new MS SQL Server Bulk Loader transform, bringing dedicated bulk loading support for one of the most requested databases. There were also plenty of improvements across the project: hidden Shell action arguments for safer logging, proper session isolation in Hop Web, fixes for
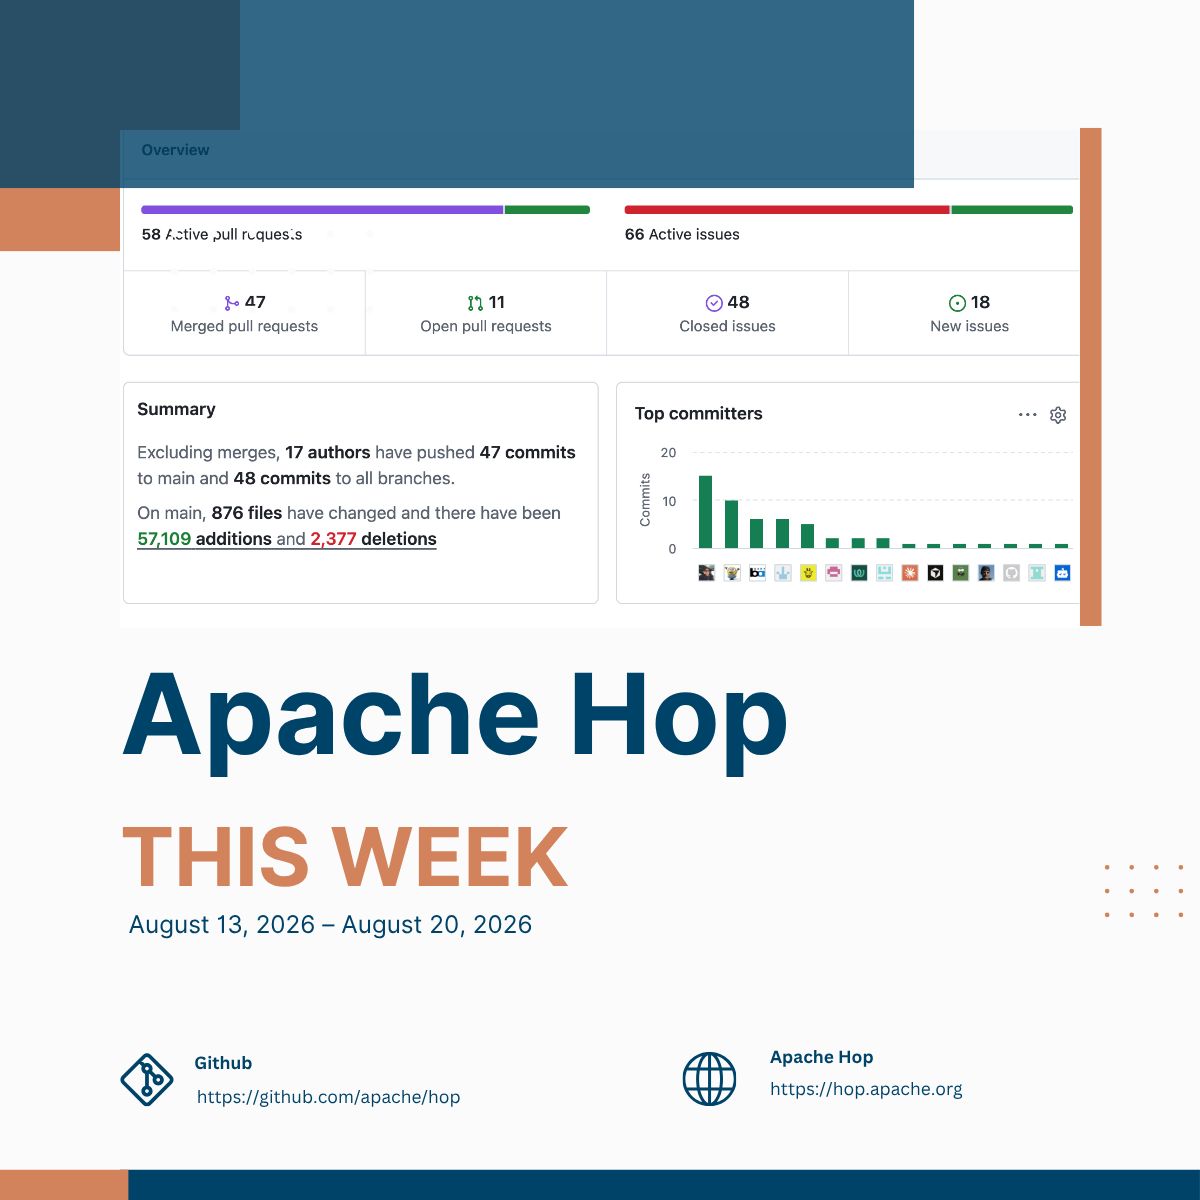
- The week after a major release is usually when things settle down. Not this time. Between Aug 13–20, the community merged 47 PRs, closed 48 issues, and saw contributions from 10 people. Apache Hop 2.19 is out, and development on the next release is already well underway. A few highlights from this week's work: 🔹 dbt Core integration is now available. 🔹 A new AWS Secrets Manager variable resolver lets you reference secrets directly from AWS Secrets Manager. 🔹 The new Multi Mapping transform makes it easier to work with multiple
- 𝗔𝗽𝗮𝗰𝗵𝗲 𝗛𝗼𝗽 𝟮.𝟭𝟵 𝗶𝘀 𝗻𝗼𝘄 𝗮𝘃𝗮𝗶𝗹𝗮𝗯𝗹𝗲. The biggest addition in this release is the new 𝗠𝗮𝗿𝗸𝗲𝘁𝗽𝗹𝗮𝗰𝗲. You can now browse, install, update, and manage plugins directly from the Hop GUI. There's plenty more in 2.19 as well: a native #Spark execution engine, support for Databricks Unity Catalog Volumes, append operations for #GCS, #Azure, and S3 file systems, SFTP metadata, plus native #Redis, #vCard support, and more. This release was put together by 22 contributors, including 6 people contributing to
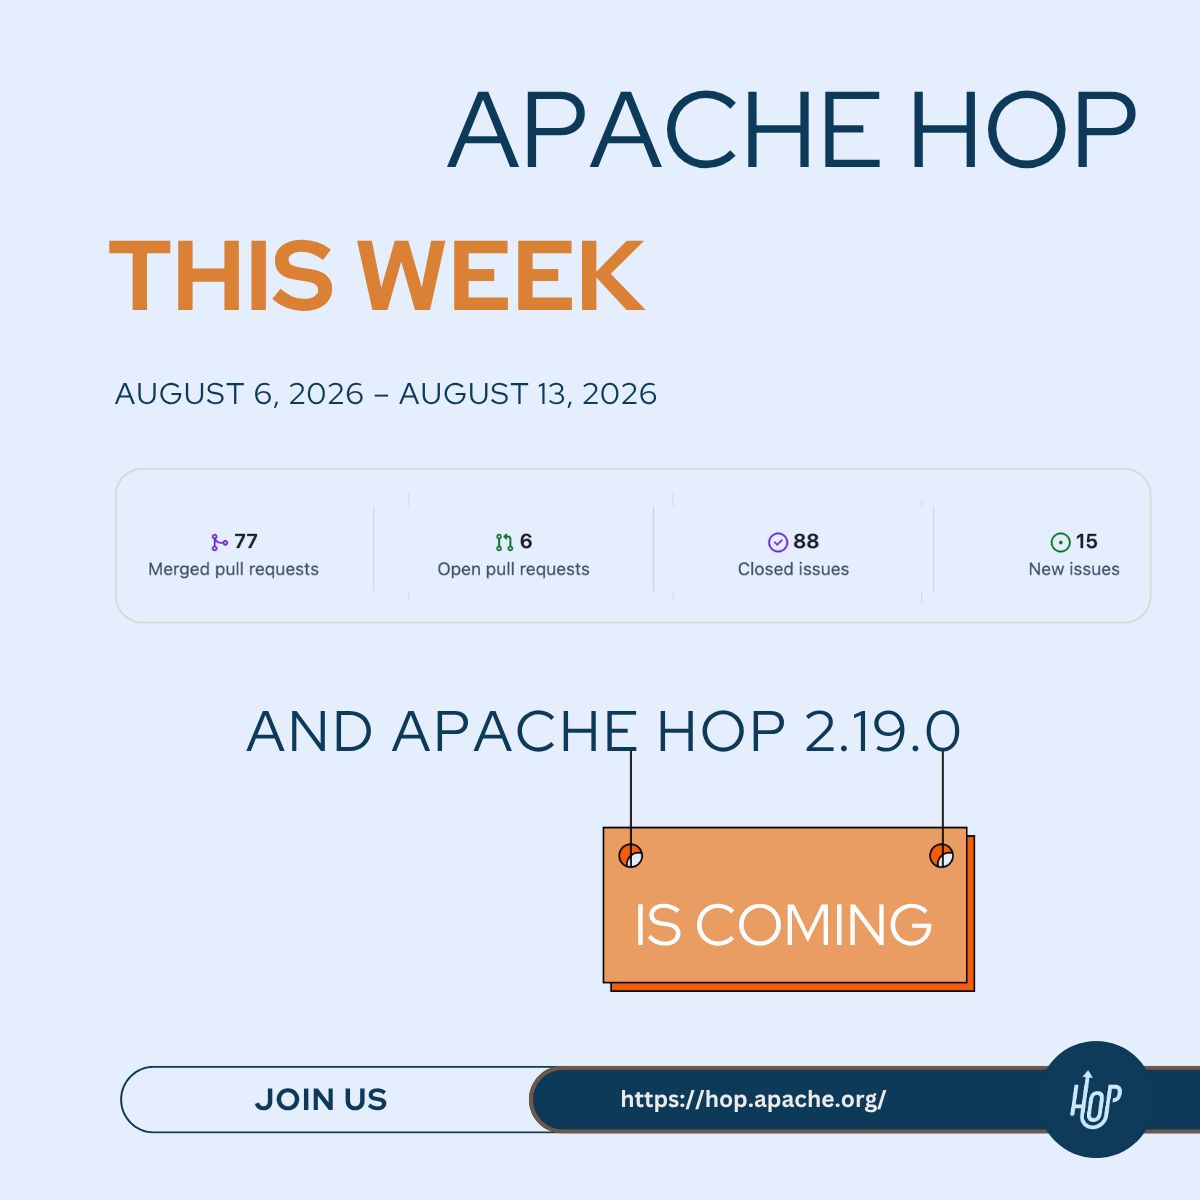
- We had a big week, and an even bigger release. 𝗔𝘂𝗴 𝟲-𝟭𝟯: 77 PRs, 88 issues closed and 2.19.0-rc1 is out. 🔹 #OpenLineage support landed. Run, file, and column-level lineage events can now be emitted to an OpenLineage sink. 🔹 JMS consumer and producer transforms are now built in, adding native message queue support. 🔹 A native #Spark SQL transform lets you write SQL directly against your Spark data. 🔹 Hop Web now includes authentication, roles, and UI authorization. 🔹 FTP/S is now a native VFS storage type, and #Azure
- 𝗝𝘂𝗹 𝟯𝟬 - 𝗔𝘂𝗴 𝟲. 𝟳𝟮 𝗣𝗥𝘀. 𝟴𝟰 𝗶𝘀𝘀𝘂𝗲𝘀 𝗰𝗹𝗼𝘀𝗲𝗱. 𝟭𝟬 𝗰𝗼𝗻𝘁𝗿𝗶𝗯𝘂𝘁𝗼𝗿𝘀. 🔹 Redis is now a first-class citizen in Hop: Input, Output, and connection metadata all in one go. 🔹 Kafka got some upgrades: read and write record headers, and read the producer topic from a field. 🔹 Markdown notes for pipelines and workflows: annotate your work directly in the canvas. 🔹 Workflow Executor now supports "workflow from field": the same flexibility Pipeline Executor already had, now available for workflows. 🔹 Drag

Something wrong or missing? Send an update. Fixed within 24 hours.