
Overview
Nodeum develops data management software focused on unstructured data autonomy and agility. The platform includes Data Mover, Storage Management, Metadata Management, Workload Manager, and Data Archiving capabilities for hybrid storage environments.
Key people
In the news
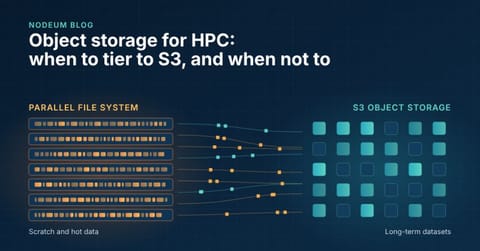
- Tier to S3 or keep it on the parallel file system? Swipe through the 8-slide test we use with HPC storage teams. The short version: move what is large, finished and rarely read to S3 object storage. Keep scratch, small-file-heavy active data and anything that needs POSIX on the parallel file system. Full article: https://lnkd.in/eH7hUe4k #HPC #ObjectStorage #DataManagement #Storage
- Moving petabytes off a parallel file system is not a migration. The data is placed somewhere else, and your users keep working while it moves. Our new article lays out a 4-phase plan for moving data to object storage without downtime: → Define the parameters and go: no months-long inventory before the first file moves → Bulk copy while the source stays live, then incremental syncs to close the gap → Verify every file with checksums: no cutover weekend, nothing to roll back Read it here: https://lnkd.in/exqcwFrp #HPC
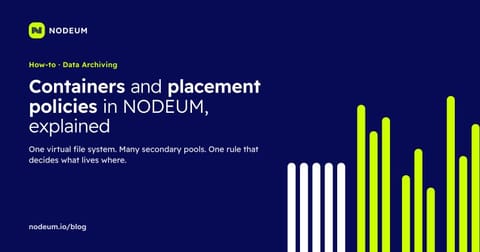
- Your users see one folder. Behind it, data can sit on disk, object storage and tape. The rule that decides where? A data placement policy. In our new how-to: → What a container is in NODEUM: one virtual file system, many storages → How secondary pools turn tape and object storage into an active archive → How a placement policy decides what lives where, and when it moves Read it here: https://lnkd.in/epyEaies #DataManagement #Archiving #DataPlacement #Storage #ResearchData
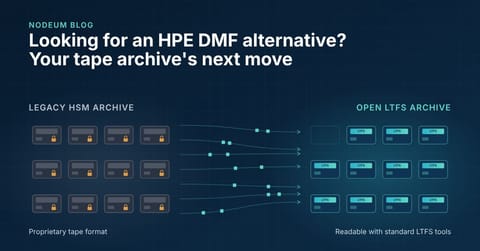
- Can you read your archive tapes without the software that wrote them? If you run application such as HPE DMF, now is a good time to check after an alternative In our new article: → What DMF does well, and what any alternative has to match → Five questions to ask before you choose your next archive → How to move off DMF in phases, without a big-bang cut-over Read it here: https://lnkd.in/eK5kyitC #HPC #Archiving #DataManagement #TapeStorage #LTFS
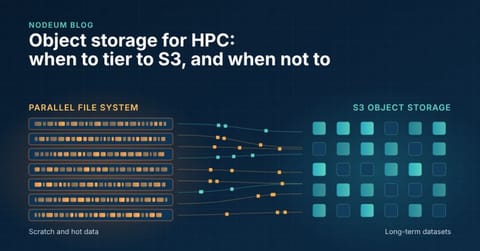
- Object storage is cheaper per TB than your parallel file system. That doesn't mean everything should live there. In our new article: → What object storage does well for HPC, and where it falls short (small files, rename, POSIX) → Which data belongs on S3: completed projects and cold results, not scratch → How to move data without disrupting users: decide what moves, keep a familiar namespace, recall on request Read it here: https://lnkd.in/eH7hUe4k #HPC #ObjectStorage #DataManagement #Storage #ResearchData
- Customers should stay with us because they want to, not because they’re stuck. I’ve spent more than 20 years around tape libraries. The drives and media almost never failed us. The problems came from proprietary formats that only one piece of software could read. That’s why we built NODEUM on LTFS. If you can mount the tape, you can read the data, with or without us. Here’s our explainer on LTFS and the archive layer 👇
- Tape is not the risk in a long-term archive. The format is. LTFS is the solution: how an open tape format keeps your archive readable, what it leaves to the archive layer, and how the two fit together. https://lnkd.in/eAhh5DA5 #Archiving #DataManagement #TapeStorage #LTFS #lockin #openformat #LTO #Tape
- Every AI budget has a line for GPUs. Almost none has a line for the data that feeds them. In our new article: → Why scattered unstructured data, not compute, slows most AI pipelines → The hidden costs: idle accelerators, untracked copies, manual movement → Five questions to ask before the next AI budget is approved Read it here: https://lnkd.in/eRKuUMFt #AIFactory #DataManagement #HPC #UnstructuredData #datamover #mobility #workflow

Something wrong or missing? Send an update. Fixed within 24 hours.