Overview
Eric Charles is the founder and CEO of Datalayer, a company that operates hosted Jupyter infrastructure for AI agents. Datalayer was founded in 2021 with a mission to make data science more accessible and collaborative. Its platform gives coding agents a persistent Jupyter notebook, direct access to data, and remote CPU and GPU compute that keeps running when the user disconnects, and it works with clients including Claude Code, Codex, Cursor, and VS Code. The company released a collaborative Jupyter platform in 2022, integrated AI assistants into data workflows in 2023, launched its Managed Agents platform in 2025, and introduced multi-agent team flows in 2026. It operates as Datalayer, Inc and describes itself as a remote-first company with contributors worldwide. He is listed as a developer and PMC member of the Apache James project and is a member of the Apache, IPython, Jupyter, JupyterLab, and Jupyter Server organizations on GitHub. In 2022, Project Jupyter named him a Jupyter Distinguished Contributor.
At the Apache Software Foundation he is listed as a developer and PMC member of the Apache James project. In the Jupyter ecosystem he is a member of the IPython, Jupyter, JupyterLab, and Jupyter Server organizations on GitHub, and Project Jupyter included him in the 2022 cohort of Jupyter Distinguished Contributors. He founded Datalayer in 2021 and leads the company as CEO, where the product has evolved from a collaborative cloud Jupyter platform in 2022 to a managed AI agents platform for data analysis.
As CEO he leads Datalayer's product, including its Jupyter MCP server, AI agents for Jupyter, and Jupyter Embed, with the platform sold both on-prem and as SaaS.
Career history

Insights & ideas
The through-line
Almost everything Eric Charles says comes back to one question: who owns the stack. He frames the arrival of managed agents as a platform shift where "most discussions focus on model quality" while "the more important question is ownership" [11], and he pushes that further by arguing that lock-in "isn't only about changing AI models" but about "your data, your workflows, approvals, integrations and business knowledge that become harder to move over time" [10]. The answer he keeps giving is architectural rather than rhetorical: standard protocols, swappable backends, open-source components, and customers who "should always own their AI stack" [9].
That conviction has stayed constant while the surface it applies to has moved outward. The early framing is about connecting agents to notebooks through a standard layer [16][15]; the later framing is about not being "locked into a single runtime path to build agentic and notebook-native products" [7], and then about hardening that work for enterprise use [1]. The same principle also shows up in how he treats his own team's work product, where results are published rather than kept, on the reasoning that "competition solutions shouldn't end with a leaderboard" [6].
On MCP as the middle ground
The case for Model Context Protocol is a case against two bad options. MCP sits between "closed SaaS solutions and custom software development" as a way to integrate capabilities such as NASA Earth data APIs and S3 buckets into an analysis workflow [15]. Without it, agents have to implement multiple external APIs directly; with it, an agent speaks one protocol while MCP servers handle the specifics of Slack, Google Drive, and Jupyter [16]. Jupyter MCP Server is the concrete expression of that: a standardized layer between agents and notebooks [16].
The practical payoff he describes for users is the disappearance of manual friction. Instead of copying and pasting code around, a user asks the AI to generate and execute code directly in the notebook, with the agent reaching external resources through tools [15]. The work has since moved from proving the pattern to making it dependable at scale, with a second version laying "the foundation for 𝗲𝗻𝘁𝗲𝗿𝗽𝗿𝗶𝘀𝗲-𝗴𝗿𝗮𝗱𝗲 Jupyter MCP" [1].
On runtime freedom and sandboxes
Multi-sandbox provider support for Jupyter MCP Server plus Code Sandboxes is presented as the direct consequence of a belief that "teams should not be locked into a single runtime path" [7]. What that buys, in his own summary, is "one MCP experience", "multiple sandbox backends", "easier movement from local experimentation to production", and "less vendor coupling, more architectural freedom" [7]. He is explicit that he does not read this as a feature release but as "a step toward more open, portable AI infrastructure that respects how developers actually work", and he asks builders in the space for feedback and real-world edge cases [7]. The same track extends to hardware access, with a first step toward giving GPU access for code execution from an agent [4].
On ownership and vendor lock-in
The architectural decision he says still guides every feature is that customers should choose their own models, connect their own tools, extend with open-source components, and keep ownership of their workflows, on the principle that "Managed AI should make you more independent—not less" [9]. The threat he identifies is slower and less visible than swapping a model: workflows, approvals, integrations and accumulated business knowledge quietly become immovable, and "those assets should belong to your organization—not your AI platform" [10]. Posed as questions to enterprises considering managed agents, it reduces to: who owns your workflows, your tools, your business knowledge [11].
On agent permissions being configurable
He raises the governance question in deliberately trivial terms, asking whether an AI agent should need approval before running a skill "even for something as simple as telling a joke" [13]. His own position is that there is no universal right answer and that the control belongs to the operator: "Personally, I believe it should be configurable" [13]. That sits naturally alongside his inclusion of approvals in the list of organizational assets that get entangled with a platform over time [10].
On document-first, spec-driven coding
After more than a year of heavy use of AI coding agents, he reports a workflow that was "mostly 𝘷𝘪𝘣𝘦 𝘤𝘰𝘥𝘪𝘯𝘨": scope a feature, sometimes write a document, hand over the context, iterate [2]. He is unambiguous that it worked, putting the productivity gain at "easily been 𝟭𝟬𝘅" [2]. The interesting move is that success did not stop him from restructuring the method, in the direction he labels vibe coding to document-first to spec-driven coding [2].
The discipline is to write the document before the code, and to make the agent work on the document first. On the Code Sandboxes provider work, rather than asking the agent to implement immediately, he asked it to review the documentation, challenge and improve it, identify what was underspecified, clarify the expected behavior, and only then start implementing [2].
On community as a privilege, not a given
He treats users who file issues and request features as the strongest signal available. Coming back from the Belgian seaside he ended up implementing community feature requests, and calls that the highlight of the weekend from a work perspective, because seeing people "use what we're building at Datalayer, ask for features, open issues, contribute ideas and push the projects in directions we hadn't necessarily anticipated is incredibly rewarding" and "tells me that the work is resonating" [5]. The caution attached to that is explicit: "having an active community is a privilege, not something to take for" granted [5]. Releases are credited outward rather than inward, to "the amazing opensource community of developers and users" [8], and to named individuals for contributions and for pushing on specific issues [4][14]. He also puts himself inside the wider builder network, joining a private gathering of builders, CTOs and engineers in Brussels [12].
On publishing the whole thing, not just the result
After a second-place finish among more than 250 teams in the ESA Φ-lab and International Charter AI for Earthquake Response Challenge, the full project went public, source code and write-up together [6]. The solution combined deep learning, image registration, Siamese networks and ensemble models to detect earthquake damage from satellite imagery [6]. The reasoning is reuse rather than credit: sharing the code so that "others can learn from it, reproduce the results, and build on top of our work" [6]. Reproducibility is the next step, with a fully reproducible version planned on the Datalayer platform so anyone can rerun the complete analysis from data prep onward [6].
Takeaways
- Judge a managed AI platform by ownership, not model quality: ask who owns your workflows, your tools and your business knowledge [11], because data, approvals, integrations and accumulated knowledge are what get hard to move [10].
- Design so customers can choose their own models, connect their own tools and extend with open-source components; "Managed AI should make you more independent—not less" [9].
- Use MCP as the middle ground between closed SaaS and building custom integrations yourself, so agents speak one protocol instead of implementing many external APIs [15][16].
- Avoid single-runtime dependency: one MCP experience over multiple sandbox backends gives "less vendor coupling, more architectural freedom" and an easier path from local experimentation to production [7].
- Before asking a coding agent to implement, make it review and challenge the document, surface what is underspecified, and clarify expected behavior [2]; the loose version already delivered "easily been 𝟭𝟬𝘅" productivity [2].
- Make agent approval requirements configurable rather than fixed, since the right threshold varies by skill and context [13].
- Publish competition work in full, code included, so results can be reproduced and built on [6].
- Treat an active community as a privilege, ship the feature requests it sends you, and credit contributors by name [5][8][14].
Media & appearances
- Cloud-Native Geospatial ForumYouTube[CNG 2025] AI Agent & MCP Servers for Jupyter to simplify Earthdata Discovery/Analysis –Eric CharlesEric Charles discusses how AI agents and Model Context Protocol (MCP) servers can simplify geospatial data discovery and analysis in Jupyter notebooks by enabling users to ask AI to generate and execute code directly rather than manually copying and pasting. He explains that AI agents use tools to access external resources like NASA Earth data APIs and S3 buckets, and that MCP provides a middle-ground approach between closed SaaS solutions and custom software development for integrating these capabilities.
- JupyterConYouTubeJupyter MCP Server: Standardizing AI Agent Access To Jupyter Notebooks - Eric Charles, DatalayerEric Charles discusses Datalayer's Jupyter MCP Server, which standardizes how AI agents access Jupyter notebooks by implementing the Model Context Protocol (MCP) as a standardized layer between agents and services. He explains how MCP solves the problem of agents needing to directly implement multiple external APIs by allowing agents to communicate through a single protocol while MCP servers handle interactions with specific services like Slack, Google Drive, and now Jupyter.
In the news
- Personal AI agents need clear rules for acting on our behalf. Meta and Sierra are developing the Personal Agent Protocol with partners including Walmart, Stripe, and Shopify—an open standard for how personal agents interact with businesses. The principle is straightforward: • Customers decide what access to grant their agents. • Businesses recognize who an agent represents and define what it can do. • Agents connect through websites, APIs, or a business’s own agent, using established standards such as OAuth and MCP. This could
- Awesome Javier Chulvi Bernad 🤩
- Intrigued how Personal Agent Protocol fits with A2A ecosystem - First time I read about it is on https://lnkd.in/eUGyfA9t by Bret Taylor - It sounds like a great initiative and hope various big and small stakeholder will have their words in the protocol definition and evolution. Excited to push further this first Python and TypeScript implementation. Looking forward feedbacks and use case 🤖 🌸 #Poppy
- After meeting twice in the US, I had the pleasure of catching up with Travis Oliphant yesterday for the third time—this time in Brussels, Belgium. Thank you, Travis, for an inspiring conversation covering so much ground, including the Intelligence Hub whitepaper and its Frames, Cogs, Ops, Guards, Gates, and Tracks constructs. I truly believe your vision and work can make a positive impact on our fast-moving world.As a concrete next step, I’ve updated Datalayer Agentspecs through two PRs to incorporate ideas from the whitepaper: 👉
- Connect with me for feedback on this announce. MCP is the enabler, we are now providing way more features on top. #Expand #Growth
- One more time, amazingly powered by the community. Plenty of great contributions here 💪⚡💚
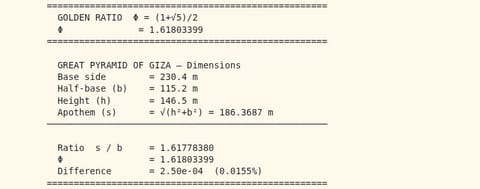
- Pyramid and the Golden Ratio The Golden Ratio (Φ ≈ 1.618) is closely approximated in the dimensions of the Great Pyramid of Giza, where the ratio of the pyramid's slant height (apothem) to half of its base length remarkably yields approximately 1.61804.
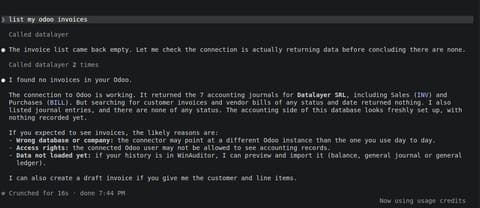
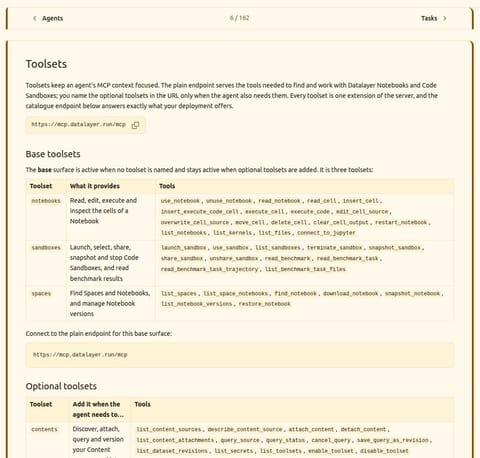
- Building at AI speed… connecting with Odoo This morning, we made the Datalayer MCP Server extensible. This afternoon, we added tools for Odoo Accounting. And the integration was surprisingly simple. What makes it different? Most MCP servers expose generic tools such as “get entity.” Datalayer lets us provide purpose-built accounting tools such as “get invoices,” making Odoo’s data much easier for AI agents—and people—to work with. Why Odoo? We’re preparing to migrate our own accounting to the platform, and giving people
Related profiles
This page shows public professional information only, each fact cited. Is this you? send a correction, or ask for removal within 24 hours, no questions asked.