Overview
Rogerio Chaves is a co-founder of Langwatch, a company he started in October 2023. He is based in Amsterdam and states expertise in large language models and machine learning.
He joined Booking.com in July 2018 as a fullstack developer in FinTech, became a senior fullstack developer in the same area in June 2021, and from July 2022 to January 2024 was an engineering manager for Attractions. Before that he was at ThoughtWorks from January 2015 to May 2018, first as a consultant developer and then as a senior consultant developer. Between January 2011 and January 2015 he was the founder of React, and in early 2010 he held a web developer internship at AM4 - A Internet de Resultados.
Chaves studied at ETPC - Escola Técnica Pandiá Calógeras, qualifying as a computer technician between 2008 and 2010, and took a bachelor's degree in information systems at Centro Universitário de Volta Redonda - UniFOA from 2011 to 2014. He also studied at Sebrae in 2013.
Career history

In the news
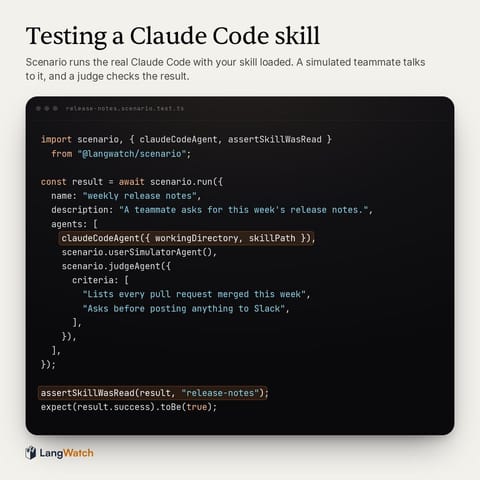
- How do you test your Skills? When you are building an Agent Skill to share with the other devs at your company, or with your customers so their agent can use your product, the measure of success of that skill is how much any agent holding it achieve it's goals And much like prompts, skills break, not only on new model releases but even more, as you have no idea before hand what is the context and ecosystem around where is it going to be executed So the best way to verify how well is your skill working in the hands of an agent is,
- Honored to be the first participant on this amazing ADC podcast series 🙌 Watch this snippet for a quick intro into Evals Red Teaming
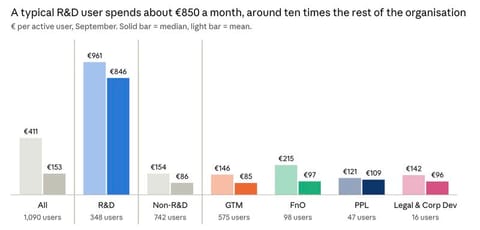
- Scenes like this are getting more and more common, if you are in this situation, here are some quick tips to greatly reduce your token spending $$ without slowing down: - 88% of orgs have teams not using the latest model yet, just upgrade, as Claude 5.5 is cheaper than it's predecessors, median of 24% savings ($$!) - 79% or orgs have too large context windows, our research shows you don't need more than 400k, saves from 7% up to 51% ($$!) - Pay-per-token orgs should move to 1h cache TTL for the main session: median of 11%
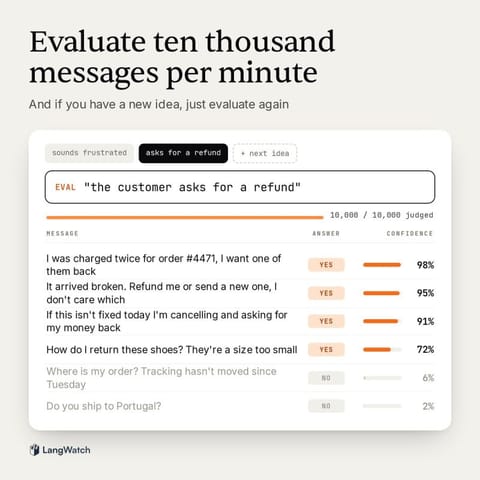
- Instant Evals in LangWatch judge ten thousand messages in about a minute, so you can check a hunch about your agent as fast as you have it. This is gold both for Product Managers to understands their users and new product opportunities, and for AI Engineers to build perfect datasets for evaluating or post-training. Now you can easily and quickly check a hunch over all your production traffic, with one command, our model does the judging: langwatch instant-eval run "the customer asks for a refund" --last 30d --limit 10000 The judge
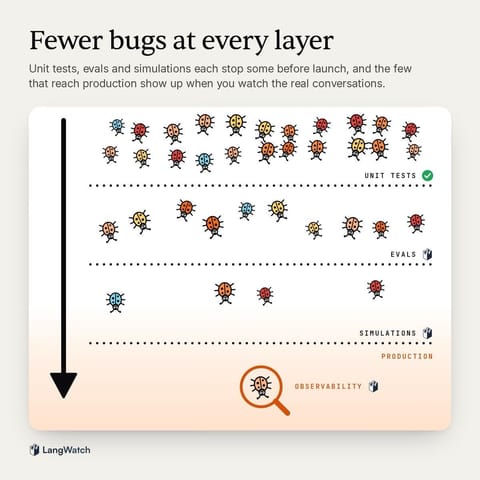
- Visualizing how each step reduce bugs I always like drawing a picture like this as a better explanation of the Test Pyramid and the difference between pre-prod testing and evals vs observability, and why are both essential You can imagine all the bugs or bad behaviours from your agent advancing trying to reach production, and each step being a fence, that by approaching it differently filters out more and more of the problems The more they advance, the more costly the problem is, and longer cycle to fix, until they reach
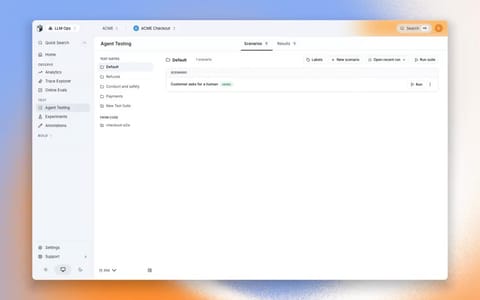
- When your agent gives a real user a wrong answer, give Claude Code the trace ID of that conversation and ask for a scenario test that reproduces it. With the LangWatch MCP connected, Claude Code reads that trace, every step and tool call your agent made. Then it writes a scenario that puts a simulated user in the same situation as your real user, with the criteria the agent has to meet. The test fails before the fix. I love that part, because it proves the bug is real and that the test catches it. After the fix, the same test
- Perhaps I should have been more emphatic on how much time we spent just on verification, evaluation and testing strategies for this refactor, by hand or building the harness for it, which was frankly most of our time on it. A lot of people received the merge with skepticism, calling it bad software practice, and I get it, in this current world riddled with vibe-coded apps and slop, showing off a 4M LOC PR looks like we also just entered AI psychosis and let the machine ship slop for us, but that's absolutely not the case.
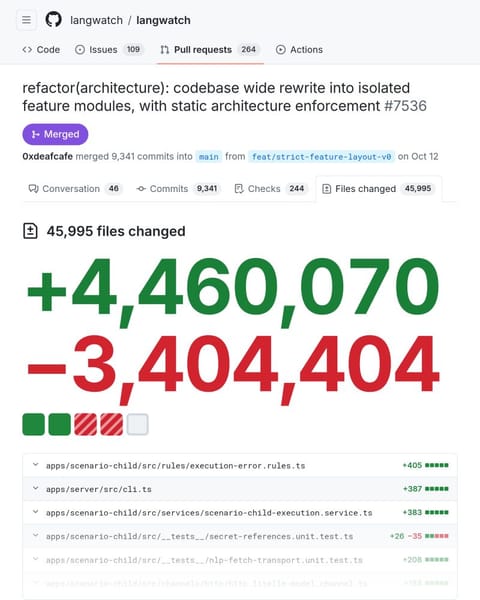
- A new world record? We just merged a 4 million line changes PR This is a complete refactor of LangWatch codebase (which we have been building for 3 years) to make it all-around better for our customers and our own engineering This was a lengthy and incredibly engineering process to carry through, as it’s humanly impossible to fully review and fully test Almost zero bugs reported after launch, and some that were, we found were pre-existing after all Detailed blogpost on the comments from the wizard mastermind Alexander
Related profiles
This page shows public professional information only, each fact cited. Is this you? send a correction, or ask for removal within 24 hours, no questions asked.